MED · Data science project
Heart Attack Prediction
Comparing six models to flag people at risk of a heart attack
- Test ROC-AUC
- 0.877
- Heart attacks caught (recall)
- 76%
- Health records
- 246,022
The problem
Only about 5.5% of people in the data have had a heart attack, so accuracy is misleading: one model here scores 93% accuracy but misses nearly half the cases. The goal is a model that catches as many at-risk people as possible and that a doctor can still understand.
The data
Personal health and lifestyle survey data, 2022, prepared by Kamil Pytlak (Kaggle) ↗
246,022 records with 40 health and lifestyle columns and no missing values
Approach
- Encoded categorical columns (ordinal, one-hot and target encoding), scaled numeric ones and engineered new features such as a heart risk score.
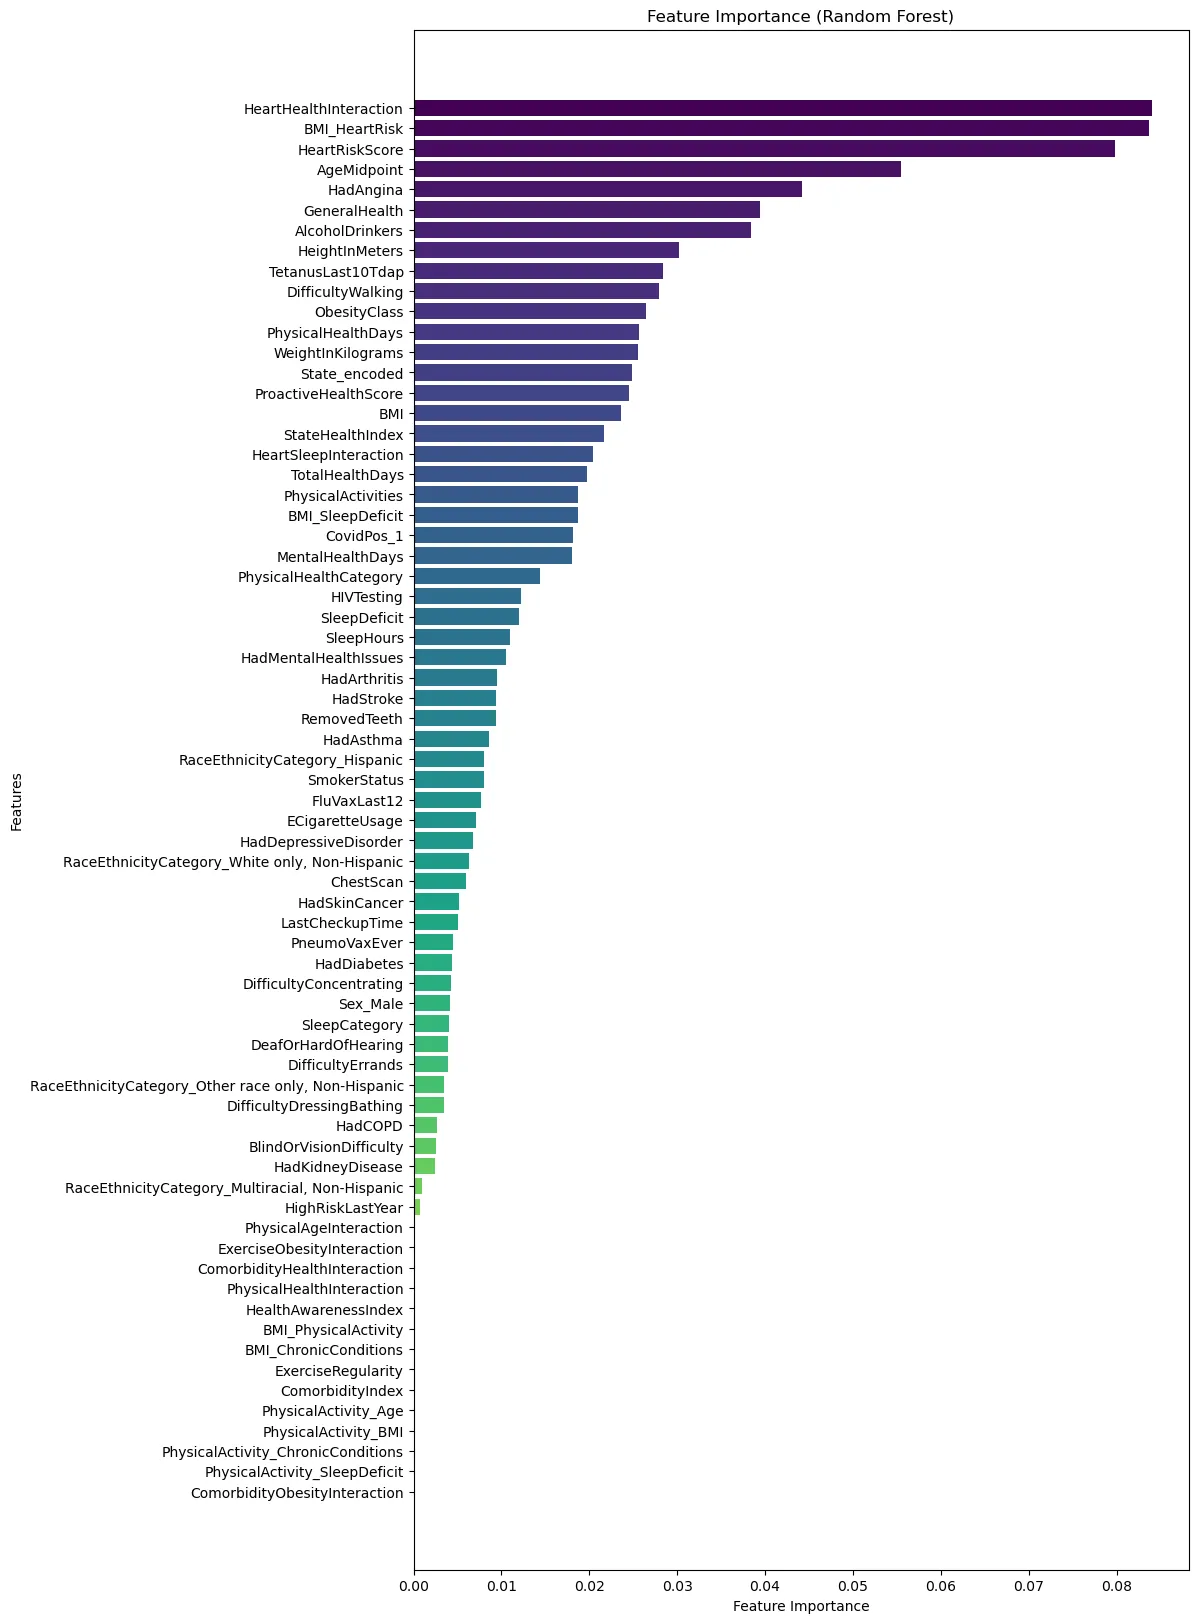
- Balanced the training data with SMOTE-Tomek and ranked features by importance and mutual information.
- Compared XGBoost, LightGBM, logistic regression, a linear SVM, a TensorFlow neural network and an XGBoost + LightGBM ensemble.
- Tuned each model with grid search and stratified k-fold cross-validation, then judged them on held-out test data.
Results
Logistic regression is the recommended model. It scored a test ROC-AUC of 0.877 and caught the most heart attacks (76% recall) while staying easy to interpret. The linear SVM had the highest accuracy (93%) but caught only 53% of cases. LightGBM scored best in cross-validation (0.943) but dropped to 0.862 on the test set.
What I'd do next
- Tune the decision threshold to cut false positives without losing recall.
- Try combining logistic regression with XGBoost and LightGBM.
Tools
- Python
- scikit-learn
- XGBoost
- LightGBM
- TensorFlow
- imbalanced-learn
- pandas